 Forenly AI Lab
Baseline rerun study: 62.0%
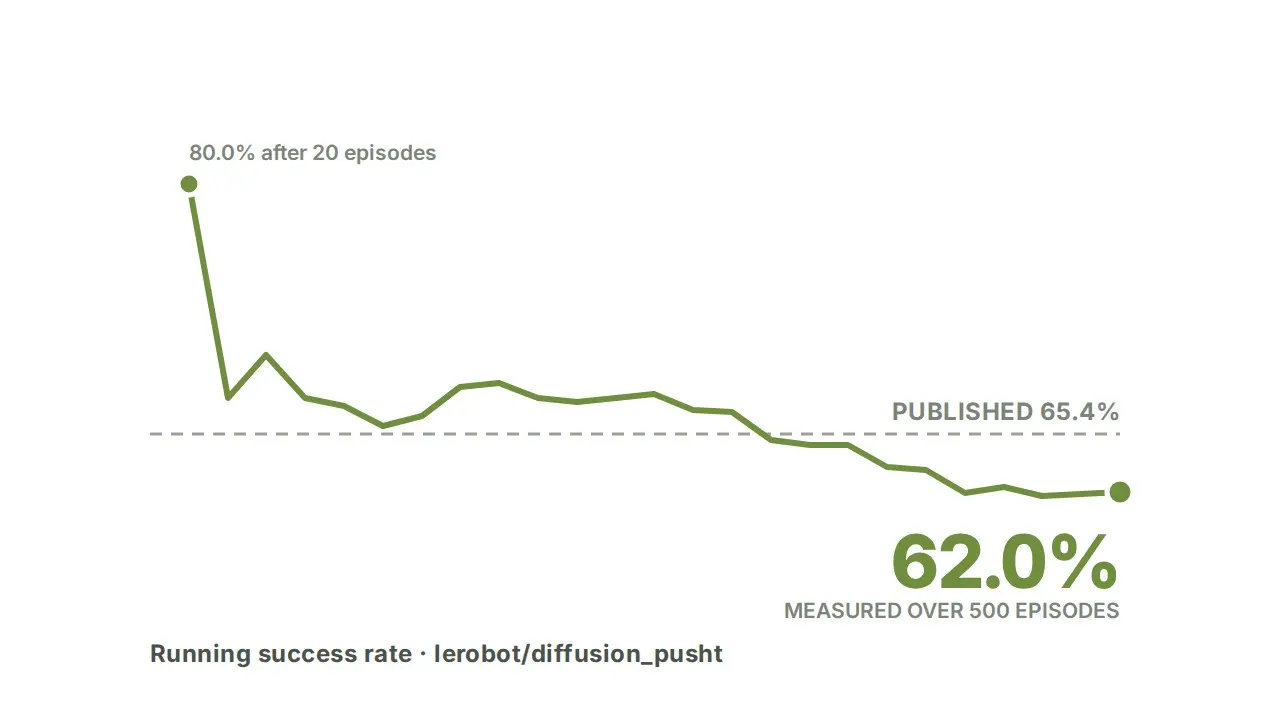
Same checkpoint, 500 PushT episodes, one fixed seed. The model card says 65.4%; we measured 62.0%, and the run read 80.0% after 20 episodes.
What we ran on 500 PushT episodes.
- Checkpoint
- lerobot/diffusion_pusht
- Task
- PushT, gym-pusht
- Episodes
- 500, seed 1000
- Stack
- LeRobot 0.3.2
- Machines
- Xeon 8 vCPU and RTX 4090
Measured, 310 of 500
On the model card
The gap, not significant at 95%
Four possible causes for the 1.6 SE gap.
- 1 · Sampling noise, most likely
A gap of 1.6 standard errors arises by chance about one run in eight.
- 2 · Another draw of episodes
The model card states no seed, and PushT randomises every reset.
- 3 · The software underneath
We ran on library versions newer than the claim; we can say least about this.
- Ruled out · Hardware
Both machines shared the seed and agree to within one episode.
The test that separates them, the same run over several seeds, is left open.
Limits of this PushT rerun.
- Not a claim the card is wrong
1.6 standard errors neither confirms nor refutes it; about 1,500 episodes would.
- We made the same mistake
An interim note called an 80-episode reading "converging". The correction stayed in the repo.
- PushT is not humanoid work
It is the first link: reproduce, measure, benchmark, humanoid, real world.
What the rerun teaches
The same run reads 80.0% at 20 episodes and 62.0% at 500: stopping early would have written another headline.